LLM Inference
These posts run small open models, mostly Qwen2.5-0.5B, on a laptop CPU or Apple GPU and print the tensors involved: token IDs, logits, cache sizes, memory per precision. No API key is needed for any of them.
Tokens and the context window come first; decoding, KV cache, quantization and batching build on them.
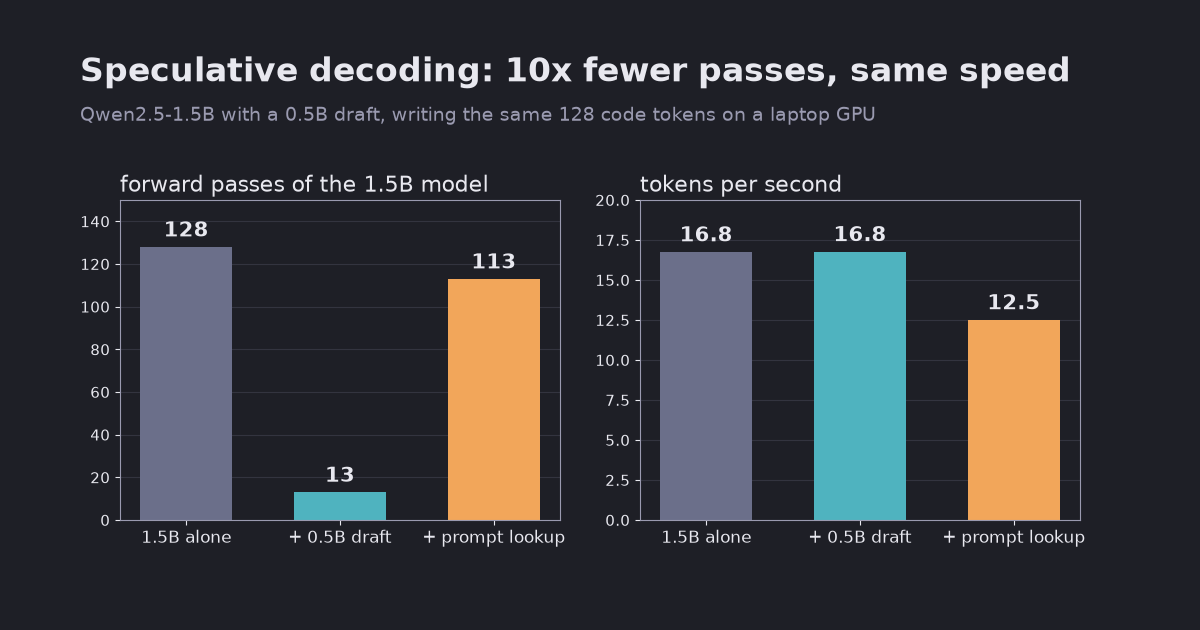
- Speculative decoding, measured on a laptop: 10x fewer model passes, no speedup
A 0.5B draft model cut Qwen2.5-1.5B's forward passes from 128 to 13 and produced exactly the same text, but tokens per second did not move. Prompt lookup decoding was 1.30x faster when the answer copied the prompt and slower otherwise. Local transformers test on an Apple M5, with the reasons.
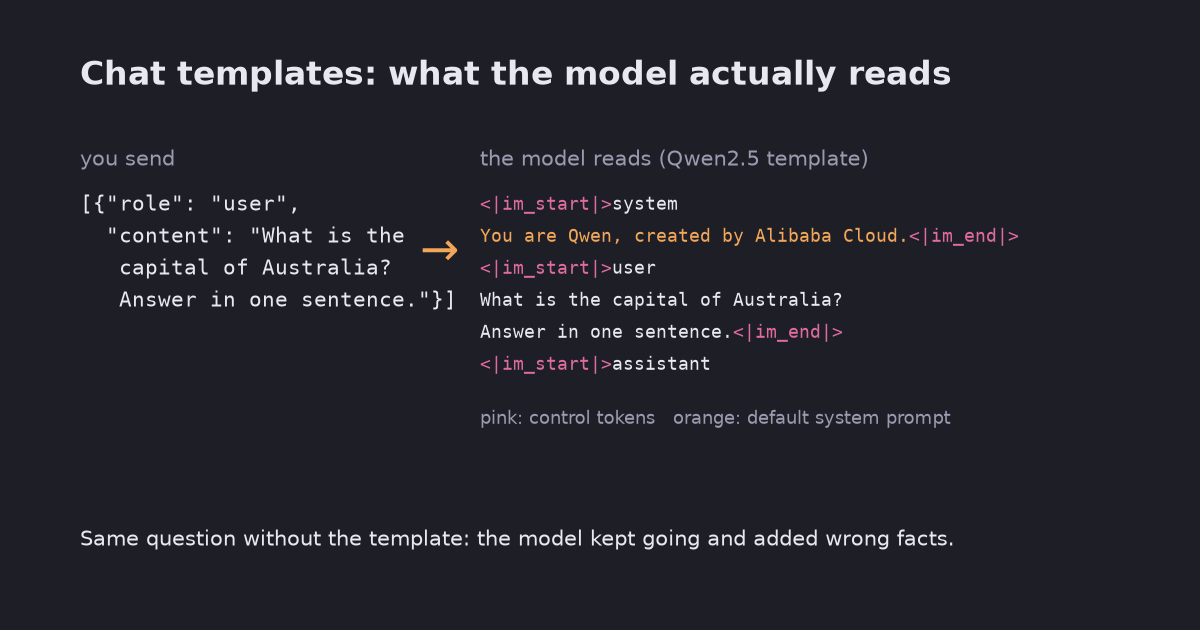
- What is a chat template? The string your LLM actually reads
A chat model never sees your list of messages. apply_chat_template turns it into one string with control tokens, and Qwen2.5 adds a system prompt you did not write. Without the template the same model rambled and added wrong facts; without the generation prompt it wrote the user's turn. Tested locally with Qwen2.5-0.5B-Instruct.
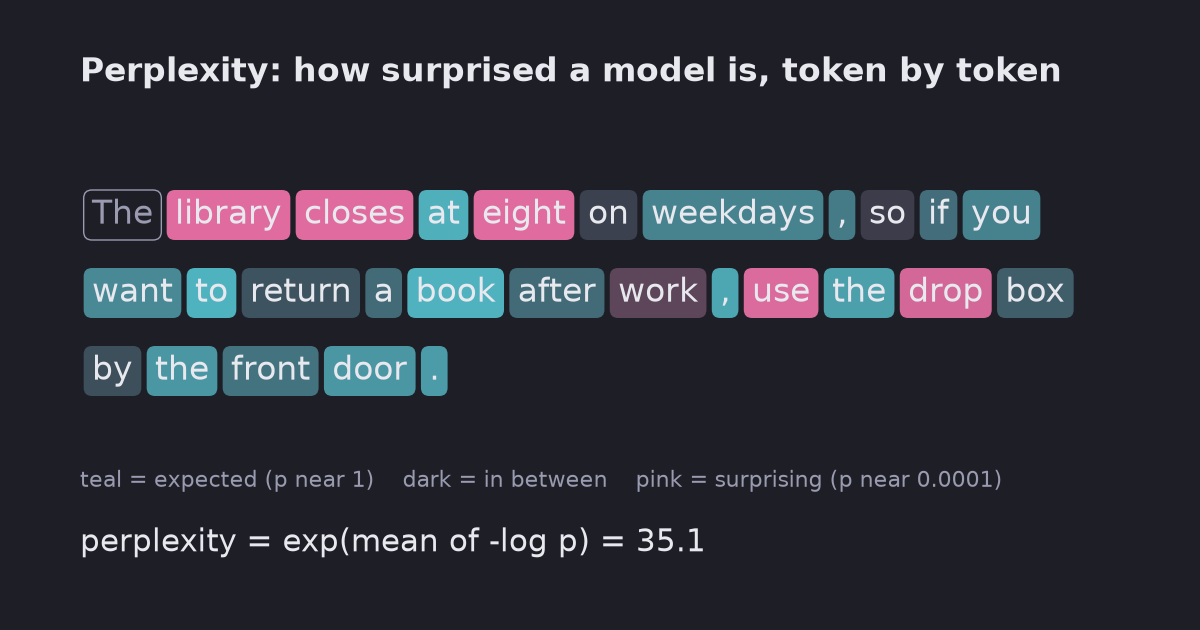
- What is perplexity? Computing it by hand with a small local model
Perplexity is exp of the average negative log-probability per token. We computed it by hand with Qwen2.5-0.5B, matched it to the library's loss, and scored five texts: a normal sentence 35.1, the same words shuffled 1,142.8, Python code 4.0. Why random letters scored lower than the shuffled sentence, and what that says about comparing numbers.
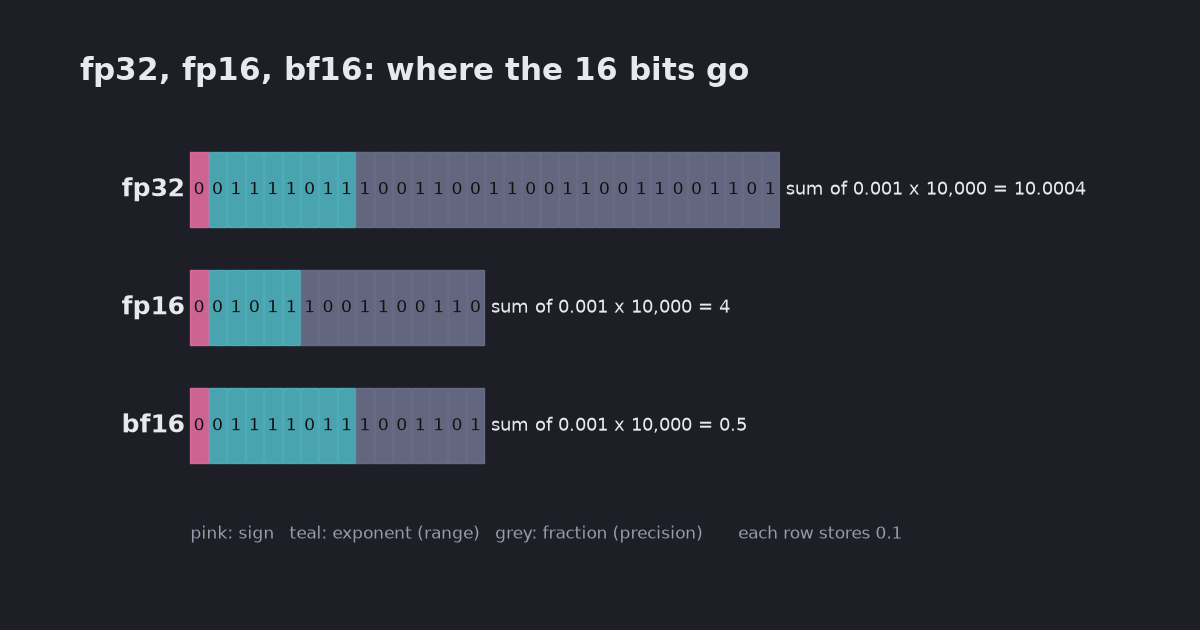
- fp32, fp16, bf16 and int8: what each format stores, and where it breaks
Models are stored in 32, 16 or 8 bits. We checked with PyTorch what each format does with the same numbers: fp16 turns 70,000 into infinity, bf16 cannot tell 1.001 from 1, and adding 0.001 ten thousand times stops at 4 in fp16 and at 0.5 in bf16. One outlier made int8 error 12 times worse.
- Greedy decoding vs beam search: why the most likely next word can give a worse answer
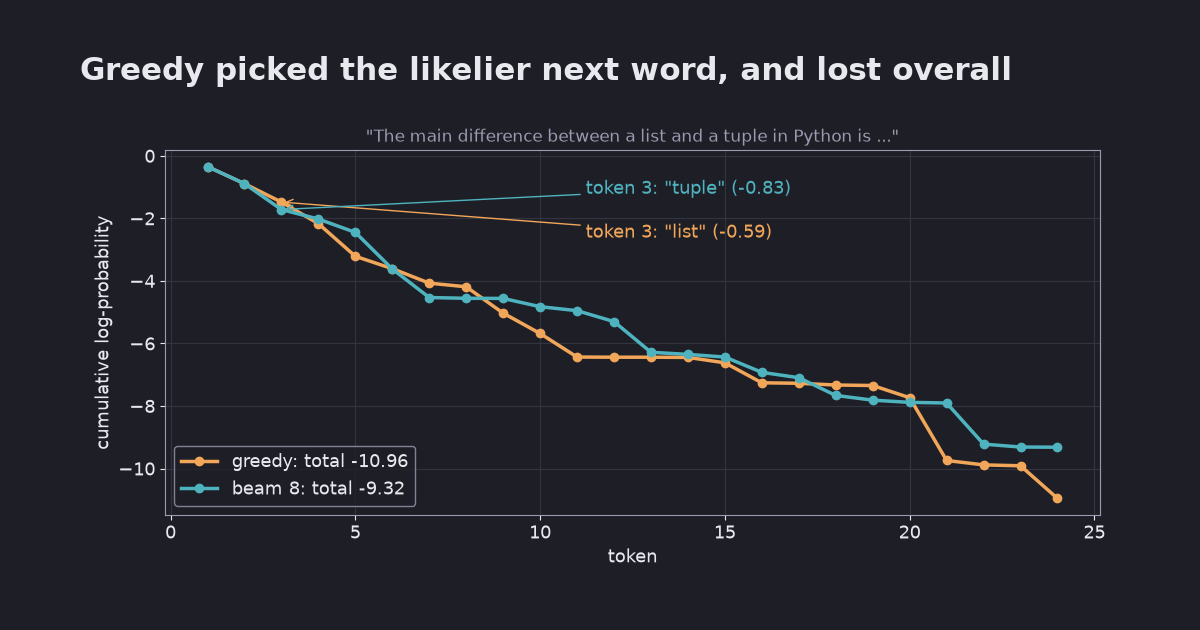
Greedy decoding picks the most likely token at every step. We compared it with beam search on a local Qwen2.5-0.5B for 10 prompts: beam search found a more probable continuation in 8 of 10, and on one prompt greedy's locally best word led to a wrong answer. Higher probability was not always better text, either.
- What is a KV cache? Memoization for LLMs, measured: 256 tokens in 7.5 s instead of 34 s
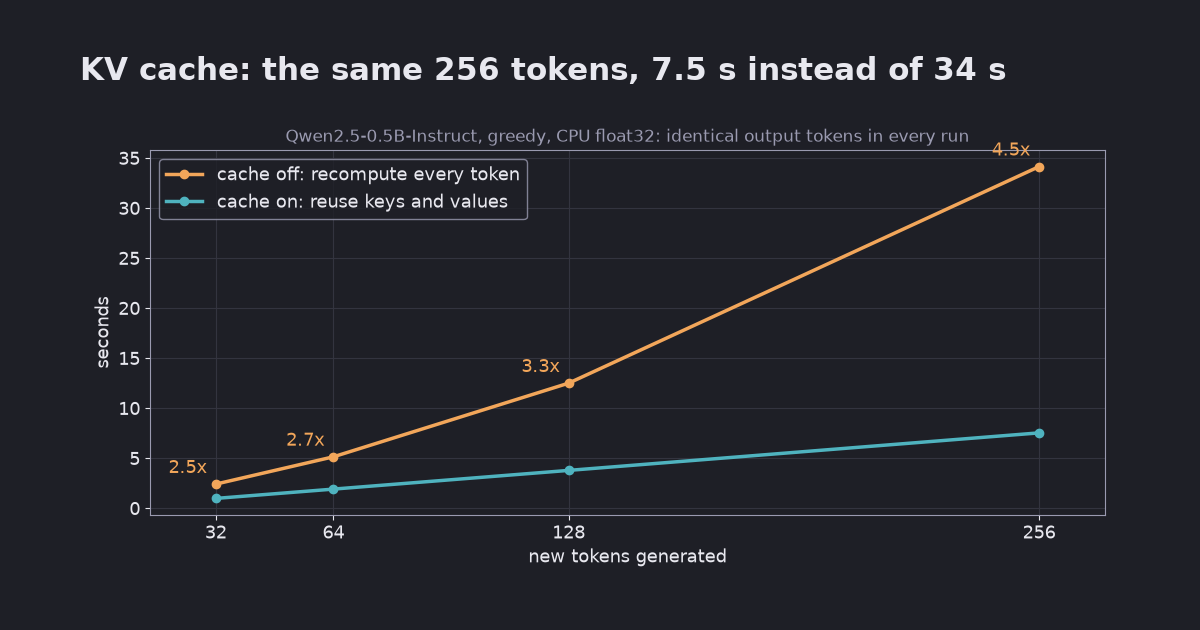
An LLM generates one token at a time, and without a cache it recomputes the whole sequence at every step. We generated the same text with a local Qwen2.5-0.5B with the cache on and off: identical tokens, 4.5x faster at 256 tokens. The price is memory, which we calculate for the same model.
- Why do LLMs miscount the r’s in ‘strawberry’? Tokens, a local test, and the fix that works
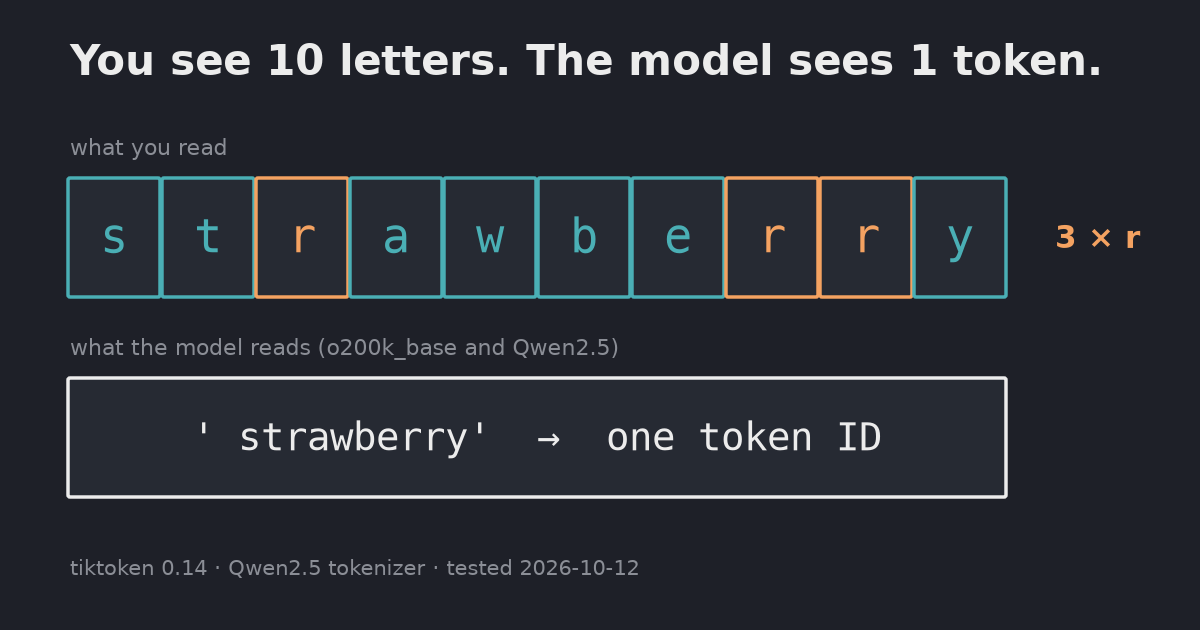
Language models read tokens, not letters: " strawberry" is a single token. We asked two small local models to count letters in three words, with and without spelling them out first. The answers were inconsistent; code was not.
- How much does quantization hurt an LLM? 8-bit vs 4-bit, tested
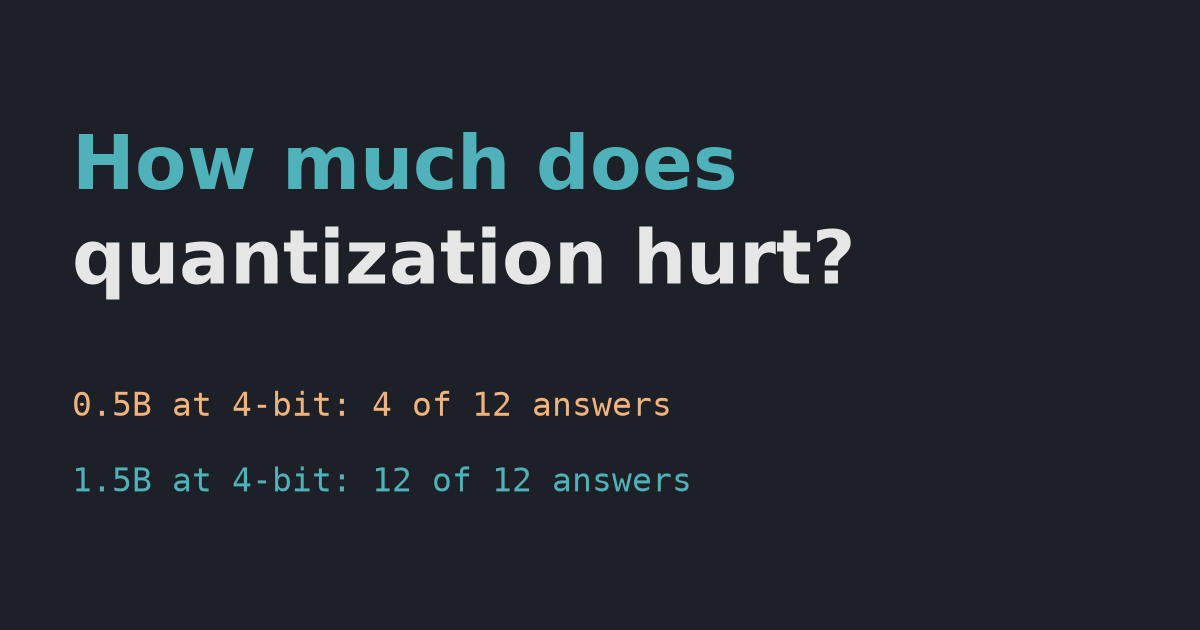
We rounded a small model's weights to 8, 4, 3 and 2 bits and measured perplexity and correct answers. 8-bit changed nothing; 4-bit dropped the 0.5B model from 11 to 4 correct answers, while a 1.5B model kept all 12.
- What is a context window, and what happens when the input is too long?
A context window is the maximum number of tokens a model can read at once. We hid a code in long documents: a small local model found it at 8,000 tokens, but answering took 35x longer than at 570, and when truncation removed the code, it made one up.
- Self-attention from scratch in NumPy (checked against PyTorch)
Scaled dot-product self-attention in 15 lines of NumPy, verified against PyTorch's scaled_dot_product_attention, with measured answers to why we divide by √d_k and why long sequences get expensive.
- What does temperature do in an LLM? Temperature, top-k and top-p explained
Temperature reshapes the next-token probabilities; top-k and top-p cut off unlikely tokens. Tested on a small open model: at temperature 2.0 the output turned into noise, and top-k fixed it while top-p did not.
- What is a token, and why do LLMs count tokens instead of words?
LLMs read text as tokens, not words or characters. We counted tokens for English, Korean, code and numbers across four tokenizers: the same Korean sentence ranged from 22 to 82 tokens.