What is a data governance framework? (with a runnable data quality check)
The six parts of a data governance framework in plain words, and what they look like in practice: a 30-line pandas check where every rule has an owner and a tolerance. Tested with pandas 3.0.
Rewritten October 2026: The first version (April 2025) only listed the parts of a framework in general terms. I rewrote it around one question, what a framework looks like when you actually run it, and added a small pandas example with real output.
TL;DR — A data governance framework is the agreement on what data rules exist, who owns each rule, and how you check them. For a small team it can start as a short list of rules, each with an owner and a tolerance, plus a script that checks them on a schedule. In the example below, 2 of 4 rules failed on an 8-row table, and each failure already had a named person to fix it.
Tested on 2026-10-07 with pandas 3.0.6, Python 3.12.
Key points
- Governance is about decisions, not tools. What counts as “good data”, who decides, and who fixes it.
- Every rule needs an owner. A check that fails with no owner is just a warning nobody reads.
- Every rule needs a tolerance. “No missing values” is rarely realistic. “At most 15% missing” is a decision someone can own.
- Start with checks you can run. A short script that runs every day beats a long policy document nobody follows.
- The tools come last. Catalogs and quality platforms help once the rules and owners exist.
What are the parts of a data governance framework?
When I first wrote this post I listed six parts. They still hold, but here they are in one line each:
| Part | In plain words | Small-team version |
|---|---|---|
| Strategy & policies | What we want from data and what we promise (security, privacy, quality) | A one-page list of rules |
| Roles & responsibilities | Who owns which data and which rule | A name next to each rule |
| Architecture & processes | How data flows from source to report | A diagram of your pipeline |
| Technology & tools | Where data lives and what checks it | Your database plus a check script |
| Metrics & monitoring | How you know the rules are kept | Pass/fail per rule, every day |
| Training & communication | How people learn the rules | A short README and a channel for alerts |
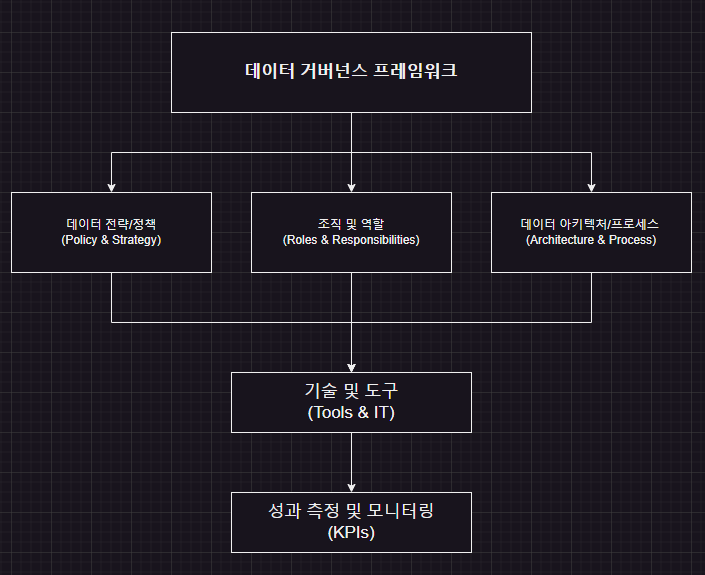
The order in the diagram matters. Policy, roles and process come first. Tools and KPIs sit at the bottom because they only work once the first three are decided.
What does it look like when you actually run it?
Like a list of rules with owners and tolerances, and a script that checks them. Here is a small orders table with a few problems planted on purpose: a duplicated order, a missing customer, and a negative amount.
import pandas as pd

# A small orders table with a few planted problems
orders = pd.DataFrame({
    "order_id":    [1001, 1002, 1003, 1003, 1005, 1006, 1007, 1008],
    "customer_id": ["C01", "C02", None, "C03", "C04", "C05", "C06", "C07"],
    "amount":      [25.0, 40.5, 12.0, 12.0, -5.0, 60.0, 33.0, 18.5],
    "country":     ["KR", "US", "KR", "KR", "JP", "US", "JP", "KR"],
    "order_date":  pd.to_datetime(["2026-10-01", "2026-10-02", "2026-10-02", "2026-10-02",
                                   "2026-10-03", "2026-10-03", "2026-10-04", "2026-10-04"]),
})

# The "policy": each rule has an owner and a tolerance (share of rows allowed to fail)
rules = [
    ("order_id is unique",      "data engineer", 0.00, lambda d: d["order_id"].duplicated(keep=False)),
    ("customer_id is filled",   "sales ops",     0.15, lambda d: d["customer_id"].isna()),
    ("amount is not negative",  "finance",       0.00, lambda d: d["amount"] < 0),
    ("country is a known code", "sales ops",     0.00, lambda d: ~d["country"].isin(["KR", "US", "JP"])),
]

report = pd.DataFrame(
    [(name, owner, f"{failed.mean():.1%}", f"{tol:.0%}", "PASS" if failed.mean() <= tol else "FAIL")
     for name, owner, tol, check in rules
     for failed in [check(orders)]],
    columns=["rule", "owner", "failed", "allowed", "status"],
)
print(report.to_string(index=False))

# Freshness is a table-level rule: is the newest row recent enough?
today = pd.Timestamp("2026-10-05")  # fixed so the output is reproducible
age = (today - orders["order_date"].max()).days
print(f"\nfreshness (owner: data engineer): newest order is {age} day(s) old, allowed 2 ->",
      "PASS" if age <= 2 else "FAIL")
Output:
                   rule         owner failed allowed status
     order_id is unique data engineer  25.0%      0%   FAIL
  customer_id is filled     sales ops  12.5%     15%   PASS
 amount is not negative       finance  12.5%      0%   FAIL
country is a known code     sales ops   0.0%      0%   PASS

freshness (owner: data engineer): newest order is 1 day(s) old, allowed 2 -> PASS
Three things in this output are the framework, not the code:
- The duplicated order fails at 25%, not 12.5%.
keep=Falsemarks both copies, because you don’t know yet which one is wrong. The data engineer gets this one. - The missing customer passes. 12.5% of rows have no
customer_id, but sales ops decided up to 15% is acceptable (for example, guest checkouts). Same data, different tolerance, different result. That decision is governance. - The negative amount goes to finance, not engineering. It might be a refund that was recorded wrongly. The owner is the person who can tell.
How should a small team start?
Small, and in this order:
- Pick the one table people complain about most. Usually the one behind an important report.
- Write five rules for it, with an owner and a tolerance each. Uniqueness, missing values, valid ranges, allowed codes, freshness.
- Run the check every day and send failures to the owner, not to a shared inbox.
- Review the tolerances once a month. If a rule fails every day and nobody acts, the tolerance or the owner is wrong.
- Only then look at tools (a data catalog, a quality platform) to scale what already works.
Common mistakes
- Starting with a tool. A catalog with no owners is an expensive list of tables.
- Rules with no tolerance. Zero missing values fails on day one and everyone learns to ignore it.
- One owner for everything. The data team can’t judge whether a refund or a guest checkout is valid.
- Writing the policy and stopping there. If no check runs, nobody knows whether the policy is followed.
Related: Why fit preprocessing on training data only? A data leakage demo · What breaks when you upgrade to pandas 3.0?