Upgrade Traps
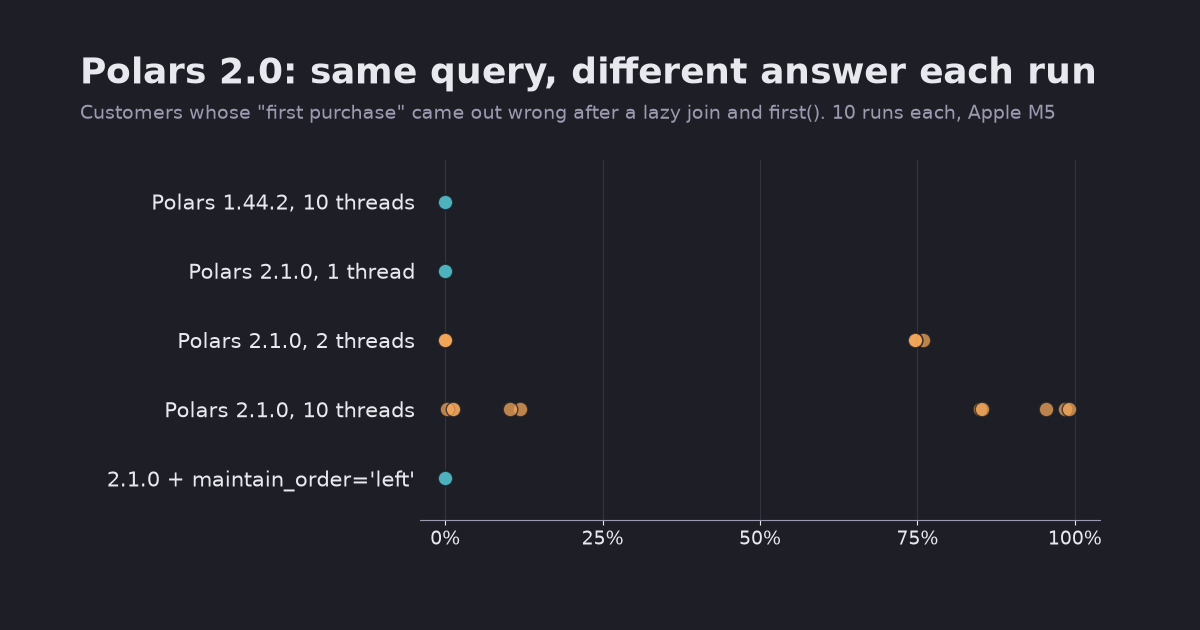
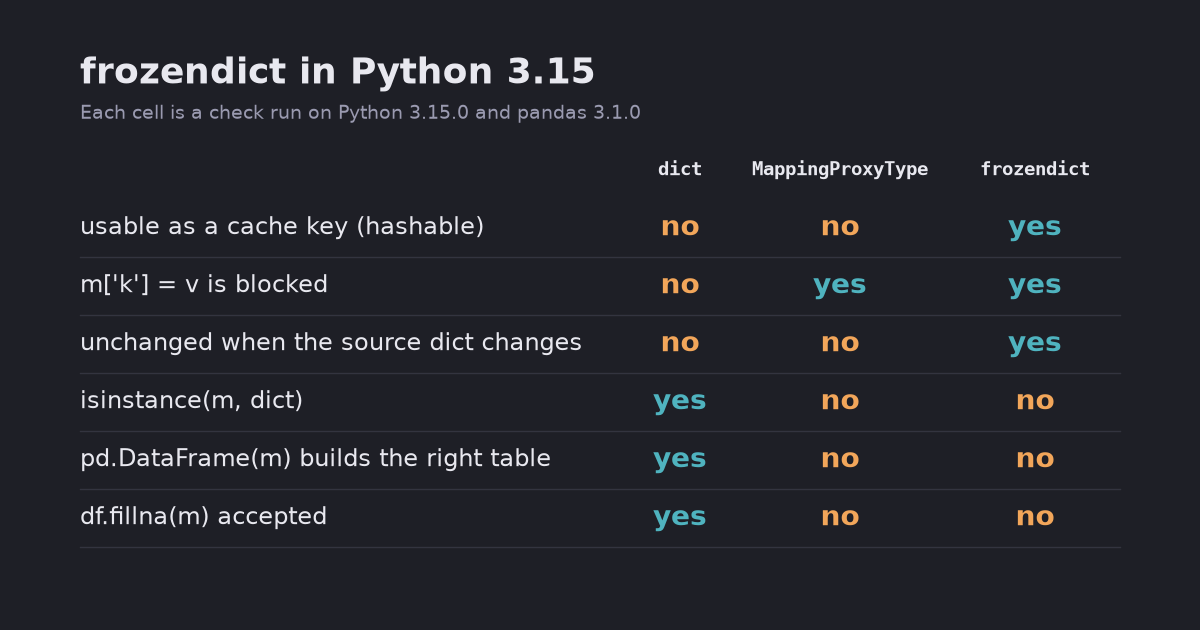
Each post here runs one script on two releases of a library and reports what changed in the output. Some of the changes raise no warning at all. In Polars 2.1 on a 10-core M5, a lazy join followed by group_by().first() picked the wrong “first purchase” in 0.2% to 99.1% of rows depending on the run, while Polars 1.44 got every row right. In Python 3.15 with pandas 3.1.0, pd.DataFrame(frozendict(a=[1, 2], b=[3, 4])) built a single column holding the keys.
The scripts behind each result are published with the post, so you can rerun them against the version you are about to install.
- Polars 2.0 upgrade: the lazy join that now returns rows in a different order
Polars 2.0 runs lazy queries on the streaming engine by default, and joins no longer keep the left row order. A "first purchase per customer" query that was right on 1.44 gave up to 99% wrong rows per run on 2.1. The fixes, plus three other changes that alter results without an error.
- Python 3.15 frozendict: when to use it, and where pandas still expects a dict
frozendict is an immutable, hashable dict that can be a cache key or a safe default argument. It is not a dict subclass, so pandas 3.1 rejects it in fillna and groupby.agg, and pd.DataFrame(frozendict) silently builds the wrong table. Tested on Python 3.15.0.
- Before benchmarking free-threaded Python, check what NumPy already does
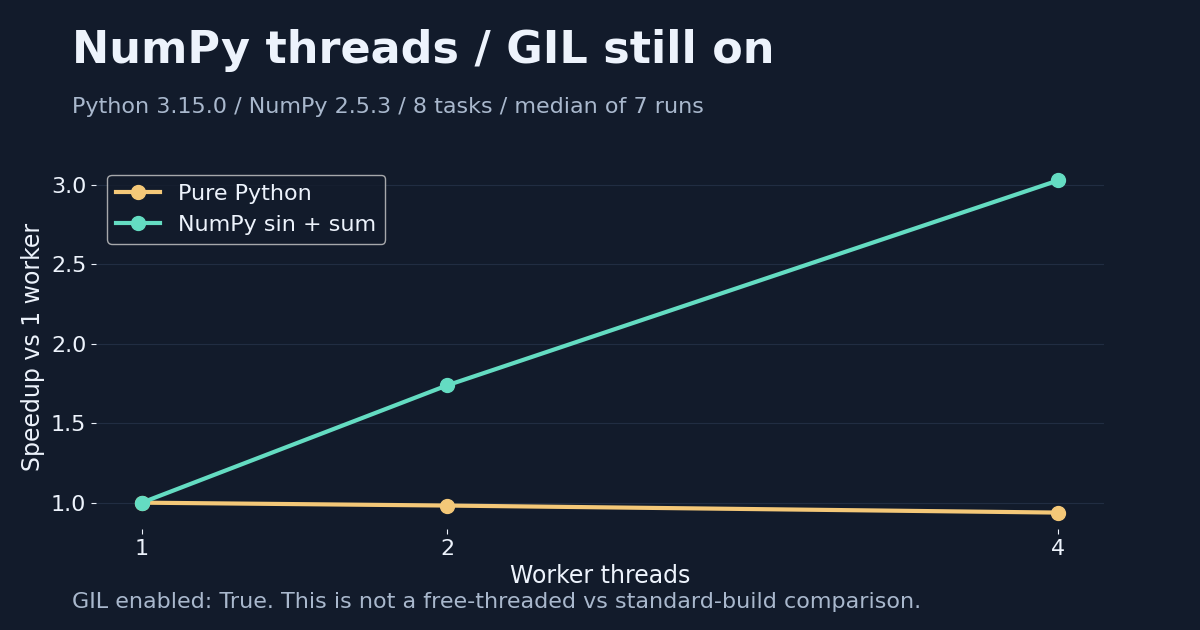
On standard Python 3.15, four threads sped up NumPy about 3x but not a Python loop. On the free-threaded build the Python loop scaled about 3x, single-threaded code ran about 14% slower, and NumPy did not change.
- Python 3.15 for data work: lazy imports, frozendict and a new profiler
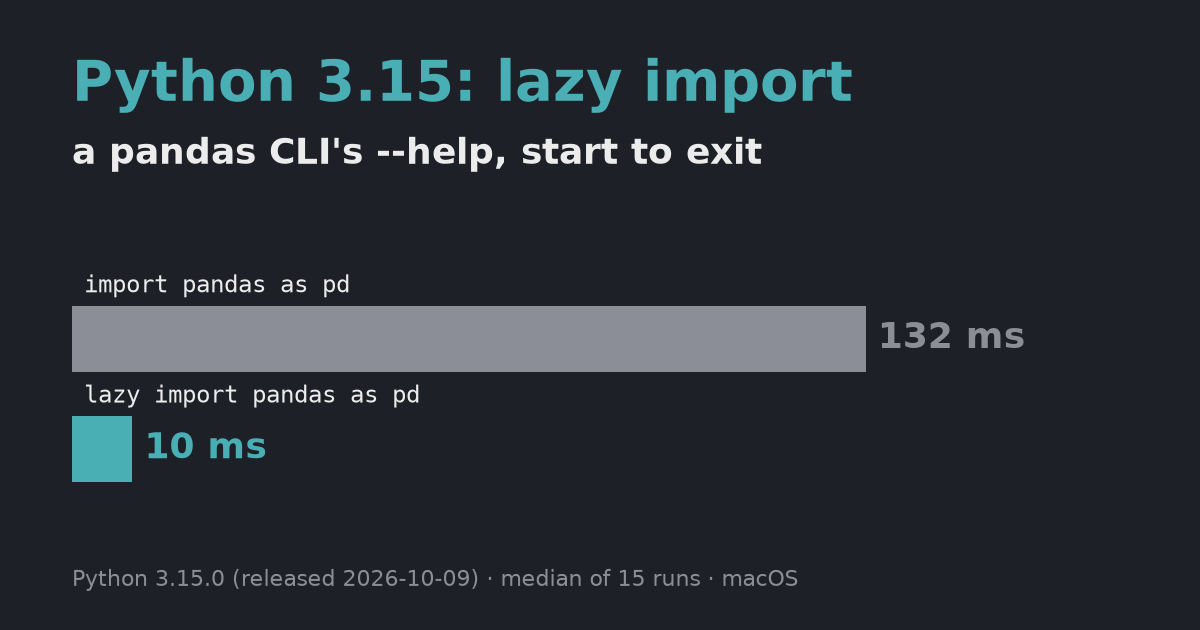
What Python 3.15 changes for data scientists, tested: lazy import cut a pandas CLI's --help from 132 ms to 10 ms, plus frozendict, unpacking in comprehensions, UTF-8 by default and the new profiling package.
- pandas vs Polars vs DuckDB in 2026: a real benchmark on 10 million rows
pandas 3.0.6, Polars 1.44.2 and DuckDB 1.5.5 on the same 10M-row dataset: read, group by, filter and join, plus a single-thread run that shows how much of the gap is just parallelism.
- How to show a progress bar in GridSearchCV (scikit-learn 1.9 callbacks)
scikit-learn 1.9 added experimental callbacks: ProgressBar for GridSearchCV and Pipeline, and ScoringMonitor for per-iteration training scores. Tested on 1.9.1, including the missing rich dependency.
- What breaks when you upgrade to pandas 3.0?
Chained assignment stops updating your DataFrame, strings get a new dtype, and datetimes switch to microseconds. Tested side by side on pandas 2.3.3 and 3.0.6.