LSTM input shape explained: (batch, timesteps, features)
What each of the three LSTM input dimensions means, how to build them from a time series with sliding windows, and the PyTorch batch_first default that silently mixes your samples. Tested with PyTorch 2.14 and Keras 3.15.
An LSTM expects a 3D input in batch-first order: (batch, timesteps, features). Batch is how many sequences you feed at once, timesteps is how many steps each sequence has, and features is how many values you have per step. In PyTorch, pass batch_first=True. Without it, nn.LSTM reads the first dimension as time, and a wrong order runs without any error.
The three input dimensions
Take 100 days of stock data with 6 columns, and predict the next day from the previous 5 days. For example, process 32 windows together, each covering the last 5 days. The features could be open, high, low, close, volume and one more variable.
| Dimension | Meaning | In this example |
|---|---|---|
| batch | Number of windows (sequences) | 95 windows, fed 32 at a time |
| timesteps | Steps in one window | 5 days |
| features | Values per step | 6 columns |
A single training batch therefore has the shape (32, 5, 6).
Build sliding windows
Slide a fixed-size window over the data. Each window becomes one sample, and the value right after it becomes the target:
The original examples were tested on 2026-09-28 with PyTorch 2.14.0, Keras 3.15.1 (PyTorch backend), NumPy 2.5.3, Python 3.12.
import numpy as np

def make_windows(data, window, horizon=1, target_col=0):
    """Turn a (time, features) array into LSTM inputs X and targets y."""
    X, y = [], []
    for start in range(len(data) - window - horizon + 1):
        X.append(data[start:start + window])
        y.append(data[start + window + horizon - 1, target_col])
    return np.stack(X), np.array(y)

daily = np.random.default_rng(0).normal(size=(100, 6))   # 100 days, 6 features
X, y = make_windows(daily, window=5)
print("X:", X.shape, " y:", y.shape)
print("first target equals day 5, column 0:", y[0] == daily[5, 0])
X: (95, 5, 6)  y: (95,)
first target equals day 5, column 0: True
100 days with a 5-day window give 100 − 5 = 95 samples. Days 0–4 predict day 5, days 1–5 predict day 6, and so on:
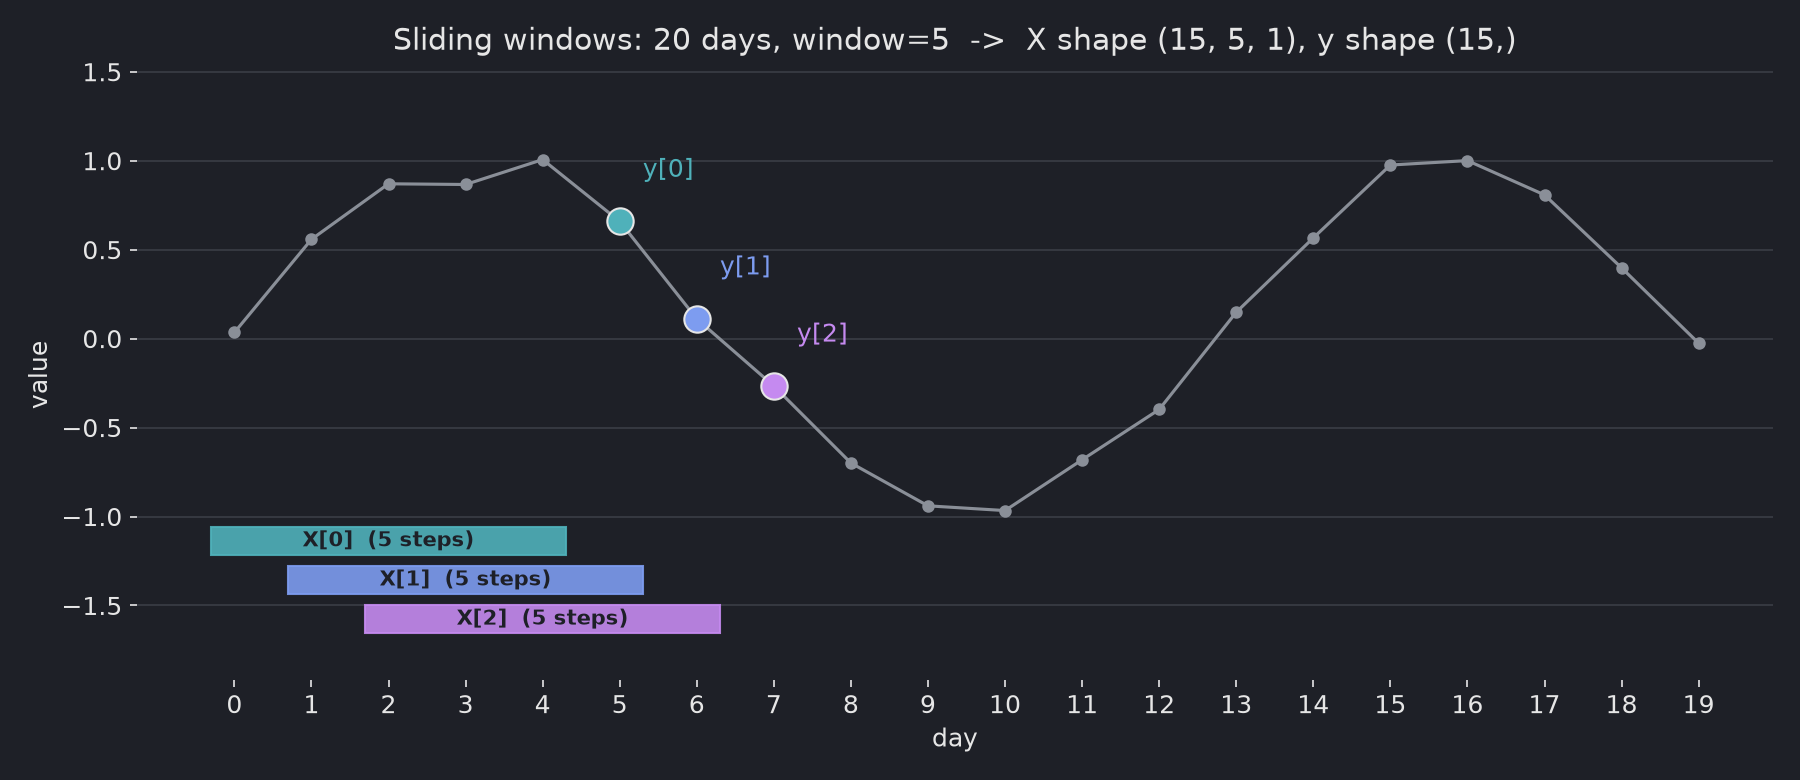
With one feature, keep the feature axis: (samples, 5, 1). An array shaped (samples, 5) has only the sample and time axes.
Why does batch_first matter in PyTorch?
Because the wrong order still runs. Here the same (32, 5, 6) tensor goes into two LSTMs:
PyTorch defaults to (timesteps, batch, features). The torch.nn.LSTM documentation describes the input/output shapes and batch_first (checked 2026-09-28).
import torch
from torch import nn

torch.manual_seed(0)
x = torch.randn(32, 5, 6)          # 32 samples, 5 time steps, 6 features

lstm = nn.LSTM(input_size=6, hidden_size=64)                    # default: batch_first=False
out, (h_n, c_n) = lstm(x)
print("batch_first=False:", tuple(out.shape), "h_n", tuple(h_n.shape))

lstm = nn.LSTM(input_size=6, hidden_size=64, batch_first=True)
out, (h_n, c_n) = lstm(x)
print("batch_first=True: ", tuple(out.shape), "h_n", tuple(h_n.shape))
batch_first=False: (32, 5, 64) h_n (1, 5, 64)
batch_first=True:  (32, 5, 64) h_n (1, 32, 64)
The output shape is identical, so nothing looks wrong. Only h_n gives it away: with the default, PyTorch treated the data as 5 sequences of 32 steps instead of 32 sequences of 5 steps. For the single-direction LSTM above, h_n has shape (num_layers, batch, hidden); the state axes also include directions in a bidirectional model.
The damage is real: the model now reads your samples as one long sequence, so each sample’s output depends on the samples before it.
import torch
from torch import nn

torch.manual_seed(0)
x = torch.randn(32, 5, 6)                 # 32 samples, 5 time steps, 6 features
x_changed = x.clone()
x_changed[0] += 1.0                       # change only sample 0

for batch_first in [False, True]:
    lstm = nn.LSTM(input_size=6, hidden_size=64, batch_first=batch_first)
    with torch.no_grad():
        diff = (lstm(x)[0] - lstm(x_changed)[0]).abs().amax(dim=(1, 2))
    others = (diff[1:] > 0).sum().item()
    print(f"batch_first={batch_first!s:<5}: changing sample 0 changed the output of {others} other samples")
batch_first=False: changing sample 0 changed the output of 31 other samples
batch_first=True : changing sample 0 changed the output of 0 other samples
With the default, changing one sample changed all 31 others. The effect shrinks along the batch (from about 0.08 for sample 1 to about 4e-08 for sample 31), but it is there. With batch_first=True, samples stay independent, as they should.
Hidden and cell state axes
Changing batch_first swaps the input and output time/batch axes. Both h_n and c_n keep (num_layers * num_directions, batch, hidden_size) for batched LSTMs with no projection. The PyTorch versioned LSTM documentation specifies these axes (checked 2026-11-17). This CPU check uses equal-length sequences, default zero initial states and no projection or dropout:
import torch
from torch import nn

torch.manual_seed(7)
x = torch.randn(3, 5, 2)  # batch, timesteps, features
for batch_first in [False, True]:
    model = nn.LSTM(2, 4, num_layers=2, batch_first=batch_first)
    model.eval()
    inputs = x if batch_first else x.transpose(0, 1)
    with torch.no_grad():
        output, (h_n, c_n) = model(inputs)
    print(f"batch_first={batch_first}: output={tuple(output.shape)}, "
          f"h_n={tuple(h_n.shape)}, c_n={tuple(c_n.shape)}")
batch_first=False: output=(5, 3, 4), h_n=(2, 3, 4), c_n=(2, 3, 4)
batch_first=True: output=(3, 5, 4), h_n=(2, 3, 4), c_n=(2, 3, 4)
Here the same batch of three sequences is transposed correctly for the default layout. In both runs, the middle state axis is the batch.
Bidirectional endpoints
A bidirectional LSTM concatenates the forward and reverse outputs at each input position. Its output width is 2 * hidden_size with no projection. For the final layer, h_n[-2] is the final forward state and h_n[-1] is the final reverse state. The reverse pass reaches its final state at the first input position. The documentation’s bidirectional notes explain this endpoint difference; the following equality checks expose it in the returned tensors.
torch.manual_seed(7)
x = torch.randn(3, 5, 2)
for bidirectional in [False, True]:
    model = nn.LSTM(2, 4, num_layers=2, batch_first=True,
                    bidirectional=bidirectional)
    model.eval()
    with torch.no_grad():
        output, (h_n, c_n) = model(x)
    print(f"bidirectional={bidirectional}: output={tuple(output.shape)}, "
          f"h_n={tuple(h_n.shape)}, c_n={tuple(c_n.shape)}")
    if not bidirectional:
        print("last output equals final hidden:", torch.equal(output[:, -1], h_n[-1]))
    else:
        final_pair = torch.cat((h_n[-2], h_n[-1]), dim=-1)
        print("last output equals final pair:", torch.equal(output[:, -1], final_pair))
        print("last forward equals final forward:", torch.equal(output[:, -1, :4], h_n[-2]))
        print("first reverse equals final reverse:", torch.equal(output[:, 0, 4:], h_n[-1]))
        print("last reverse equals final reverse:", torch.equal(output[:, -1, 4:], h_n[-1]))
bidirectional=False: output=(3, 5, 4), h_n=(2, 3, 4), c_n=(2, 3, 4)
last output equals final hidden: True
bidirectional=True: output=(3, 5, 8), h_n=(4, 3, 4), c_n=(4, 3, 4)
last output equals final pair: False
last forward equals final forward: True
first reverse equals final reverse: True
last reverse equals final reverse: False
In the single-direction run, output[:, -1] and h_n[-1] are equal. In the bidirectional run their shapes are (3, 8) and (3, 4), respectively: the last output includes both directions, while h_n[-1] selects the reverse direction alone. Even after concatenating the final hidden states into a matching-width final_pair, equality with the last output is False. The forward half comes from the last input position; the final reverse half comes from the first input position. For a sequence-level head using both completed passes, feed final_pair.
Both added checks ran on 2026-11-17 with CPU float32, PyTorch 2.14.0, Keras 3.15.1 installed with the PyTorch backend, NumPy 2.5.3 and Python 3.12.13 on macOS arm64. The complete state-check script and recorded output reproduce these two blocks.
Keras input and sequence outputs
Keras always uses batch-first order and leaves the batch size out of Input:
keras.Input(shape=(5, 6)) means 5 timesteps and 6 features. The Keras LSTM layer documentation describes return_sequences (checked 2026-09-28; rechecked 2026-11-17).
import os
os.environ["KERAS_BACKEND"] = "torch"
import keras

inputs = keras.Input(shape=(5, 6))                  # (time steps, features); batch is left out
seq = keras.layers.LSTM(64, return_sequences=True)(inputs)
last = keras.layers.LSTM(64)(seq)
model = keras.Model(inputs, keras.layers.Dense(1)(last))
for layer in model.layers:
    print(f"{layer.name:<10} {layer.output.shape}")
input_layer (None, 5, 6)
lstm       (None, 5, 64)
lstm_1     (None, 64)
dense      (None, 1)
None is the batch dimension. return_sequences=True keeps one output per timestep, (None, 5, 64), which the next LSTM needs. The last LSTM returns only the final step, (None, 64).
For stateful Keras setups, see LSTM 의 Input Shape정리 — Keras batch_input_shape and stateful LSTMs (in Korean).
Shape errors and fixes
| Symptom | Cause | Fix |
|---|---|---|
PyTorch: input.size(-1) must be equal to input_size. Expected 1, got 5 | One feature without its own axis, e.g. (95, 5). PyTorch reads a 2D tensor as one unbatched sequence | X[..., None] or X.reshape(-1, 5, 1) |
| Model trains, results look odd, no error (PyTorch) | (batch, seq, feature) data without batch_first=True | nn.LSTM(..., batch_first=True) |
| Shape error between stacked LSTMs (Keras) | Earlier layer returns only the last step | return_sequences=True on all but the last LSTM |
| Target is one step off | Window and target indices misaligned | Check y[0] against the raw data, as above |